emmtrix
Edge AI Compiler
(eAI)
Generate Target-Aware C Code from AI Models for Embedded Systems
Your AI model is trained. The next challenge is deploying it efficiently in an embedded software workflow.
The emmtrix Edge AI Compiler transforms ONNX and PyTorch models into software optimized for efficient execution on embedded and edge hardware. It analyzes and transforms the model, applying target-aware optimizations to generate deployment-ready code for the selected platform.
For processor vendors, emmtrix can on request adapt the compiler to a specific architecture and toolchain and provide a white-label solution for their customers.
This enables engineering teams to integrate high-performance AI inference into existing embedded software workflows—without relying on a large, general-purpose inference runtime as the central integration layer.
Evaluate the Edge AI Compiler Workflow
Download the one-page product flyer for a compact technical overview to pass on to colleagues/management or request a demo to discuss your model format, toolchain, and target architecture with our technical team.
Working on a space application? Explore the Edge AI Compiler workflow for embedded AI deployment in space systems.
AI Workflow: From ML Model to Target-Aware C Code
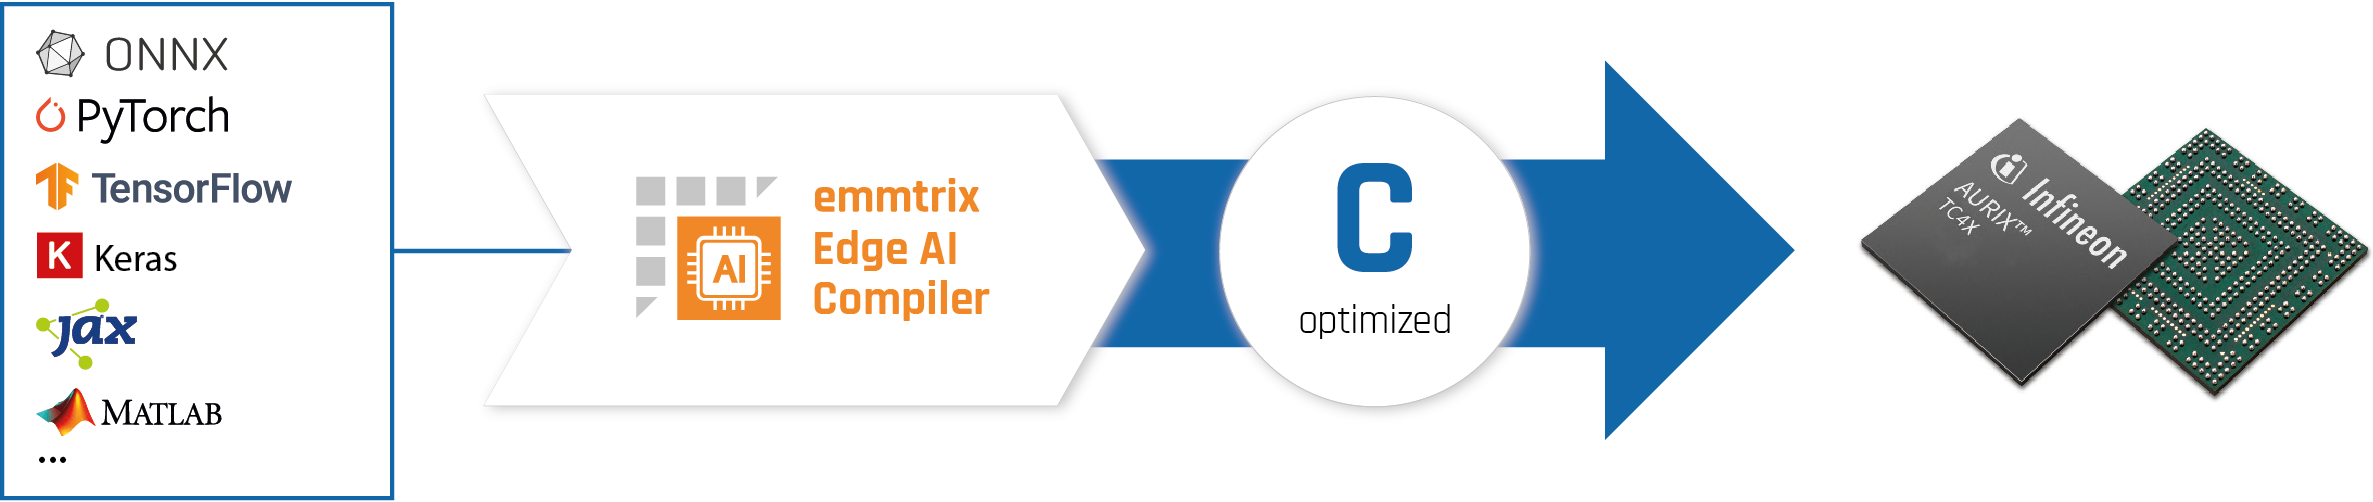
Figure 1: emmtrix Edge AI Compiler Workflow
The emmtrix Edge AI Compiler provides an automated, target-aware workflow for deploying trained neural-network models on embedded and edge hardware. Starting from ONNX or PyTorch models, it systematically restructures and optimizes the inference workload for the selected target platform.
The workflow combines memory and data-access optimization, control-flow simplification, loop restructuring, kernel fusion, and automatic vectorization. It can generate target-specific implementations using vector intrinsics and, where available, dedicated accelerators—enabling efficient execution on platforms such as Infineon AURIX™ TC4x with its Parallel Processing Unit (PPU), Arm processors with NEON or SVE, and RISC-V processors with RVV.
The resulting implementation is ready to compile with the target’s standard C toolchain and integrate into established embedded software workflows. Numerical behavior can be validated against ONNX Runtime reference results, supporting a dependable path from trained model to deployed inference application.
For Processor Vendors and Embedded AI Teams
Processor and Chip Vendors
emmtrix can adapt the Edge AI Compiler to a processor architecture, instruction set, accelerator and toolchain. A specific version can be developed as a white-label solution for the vendor’s customers. The scope of target support and integration will be defined together with the customer for each project.
Embedded AI Developers and Development Teams
Teams deploying trained models can use the compiler workflow to generate C code for an embedded target. If the available target support does not cover their hardware or toolchain, emmtrix can offer adaption services.
Key Features
- Automatic Model Conversion: Seamless translation of ONNX and PyTorch models into portable C code.
- Loop Optimization and Kernel Fusion: Loop normalization, fusion and simplified control flow to prepare generated code for downstream optimization.
- Memory Footprint Reduction: Tensor memory is planned at compile time. A shared memory pool allows memory to be reused when tensors are no longer needed, reducing the required memory where reuse is possible and making tensor memory use predictable during inference.
- Hardware-Aware Code Generation: Generation of target-specific C code using intrinsics, SIMD capabilities and hardware-specific optimization techniques where applicable.
- Deterministic Execution: Predictable code generation and execution characteristics designed for embedded deployment workflows.
- Validation Support: Validation of generated C code against ONNX Runtime reference behavior in ONNX-based workflows.
Key Benefits
The key benefit is reducing the manual work between a trained AI model and efficient execution on the selected target platform.
- Less Manual Optimization Work
Reduce the effort required to prepare generated C code for a specific embedded processor. - Code Built for the Target Platform
Generate C code tailored to the selected architecture instead of relying only on generic generated code. - Fits Existing C Workflows
Integrate generated code into existing embedded software projects, compiler workflows, and build environments. - Less Dependency on Inference Runtimes
Deploy AI workloads through generated C code instead of making a dedicated inference runtime the central integration layer. - A Repeatable Deployment Process
Apply the same structured workflow from model input to generated target-specific C code across projects.
Public Evidence
emmtrix provides public technical evidence for the Edge AI Compiler workflow and related tool components.
98.17% ONNX Backend Coverage
emx-onnx-cgen 1.2.2 reached 98.17% ONNX Backend Coverage against ONNX 1.20.1 on the stable-build scoreboard dated 2026-03-25. This should be understood as a versioned, time-stamped compatibility indicator.
Infineon Associated Partner
emmtrix Technologies is an Infineon Associated Partner with over 10 years of experience working with the Infineon AURIX™ microcontroller family and has been actively collaborating with Infineon for the past five years.
This partnership is relevant for teams evaluating AURIX-based embedded AI deployment, vectorization and target-aware optimization workflows.
Conference Talk
ONNX Community Meetup 2026
At the ONNX Community Meetup 2026, Dr. Timo Stripf presented lessons learned from building an ahead-of-time ONNX-to-C compiler.
The talk provides technical background on emx-onnx-cgen, the open-source ONNX-to-C compiler used in the emmtrix Edge AI Compiler workflow.
Supported Platforms
The emmtrix Edge AI Compiler workflow supports target-aware code generation and vectorization for a range of embedded and edge architectures.
Currently supported target families include:
- Infineon 32-bit TriCore™ AURIX™ TC4x MCUs,
- ARM Cortex A cores with Neon or Scalable Vector Extension (SVE)
- instruction sets
- x86 processors with the Advanced Vector Extensions (AVX)
- RISC-V “V” Vector Extension (RVV).
Additional architectures can be discussed based on project requirements.
Dive deeper: Learn how emmtrix supports RISC-V RVV vectorization using the official RISC-V Vector C Intrinsics v1.0.
Cortex-A
(NEON/SVE)
ix86
(AVX)
Supported Compilers and Vector Programming Models
Vector instructions are exposed differently across processor families and compilers. A practical vectorization workflow must therefore support different C programming models as well as a broad range of SIMD instruction sets.
The emmtrix Edge AI Compiler workflow supports target-aware C code generation using:
- Inline Assembly: For fine-grained hardware control where required.
- Platform-Specific Intrinsics: Compiler-provided functions for accessing target-specific vector features.
- Compiler-Specific Vector C Extension with Intrinsics: Vector data types and overloaded operators combined with platform-specific intrinsics to balance readability, portability and target-specific optimization.
The workflow supports SIMD vectorization for architectures including x86 with AVX2, Arm with NEON and SVE, and RISC-V with the RISC-V Vector Extension (RVV). Where applicable, it can also use dedicated vector accelerators such as the PPU in Infineon AURIX™ TC4x devices. The workflow typically uses the most abstract suitable programming model to keep the generated code readable while still fitting the target compiler and architecture.
Relevant compiler and environment contexts include TASKING SmartCode, Synopsys ARC MetaWare, GCC Vector Extensions and Clang Vector Extensions.
Frequently Asked Questions
Which model formats are supported?
The documented workflow supports ONNX models and PyTorch workloads. ONNX-based workflows can use emx-onnx-cgen. PyTorch-based workflows can use emx-pytorch-cgen.
What kind of C code is generated?
The Edge AI Compiler generates target-specific C code for embedded inference. It automatically optimizes ONNX and PyTorch models for memory use, execution flow and the selected hardware. The result can use SIMD instructions, vector extensions or dedicated accelerators and integrates with standard embedded C toolchains.
Does generated C require a large inference runtime?
The workflow is designed to reduce dependency on a large inference runtime as the central deployment layer. Generated C can be integrated into existing C-based embedded software workflows.
Can generated C be validated?
Yes. For ONNX-based workflows, generated C can be validated against ONNX Runtime reference behavior. This helps teams compare generated code with expected model behavior before further optimization or deployment.
Which target architectures are referenced?
Currently referenced target families include AURIX TC4x PPU, ARM NEON/SVE, RISC-V Vector Extension and x86 AVX. Other targets can be discussed for evaluation.
Can the compiler be adapted for a new processor architecture?
Yes. emmtrix can assess adaptation to a processor architecture, instruction set, accelerator and target toolchain. The required work and supported features depend on the hardware and the project requirements.
Is a white-label solution available for processor vendors?
A target-specific white-label version can be developed for processor vendors that want to provide an AI deployment workflow to their customers. Branding, target support, integration and validation requirements are agreed for the individual project.
Which compilers and toolchains are relevant?
Documented compiler and environment contexts include TASKING, Synopsys, GCC, LLVM, simulators, hardware verification and CI-oriented workflows.
Is the workflow suitable for safety-oriented environments?
The workflow supports generated code that is reproducible, reviewable and suitable for validation against reference behavior. Whether it fits a specific safety process depends on the project, toolchain, validation requirements and qualification context.
What public evidence exists for ONNX compatibility?
emx-onnx-cgen 1.2.2 reached 98.17% ONNX Backend Coverage against ONNX 1.20.1 on the stable-build scoreboard dated 2026-03-25. This should be treated as a versioned, time-stamped compatibility indicator.
What information is needed for an evaluation?
A useful evaluation usually only requires the model and the target compiler and access to simulator or hardware environments where applicable.
For deeper technical explanations, see the emmtrix Edge AI Compiler Technical Wiki.
Technical Wiki and Implementation Details
For implementation-level details, compiler integration guidance, vector programming models and platform-specific background, visit the emmtrix technical wiki.
Let’s Get in Touch
Tell us about your model format, target architecture, toolchain context and validation requirements.
If you have specific requirements regarding a target processor or a white-label solution, please include the architecture, toolchain, and intended integration context.
We also offer technical consultations to discuss your deployment scenario, assess whether the emmtrix Edge AI Compiler is suitable for your requirements, support the selection of suitable hardware and software components, and identify appropriate next steps.